网页
综合
更新时间 2026-11-13 15:51:35
Blog
Making developers awesome at machine learning
Making Developers Awesome at Machine Learning
Making developers awesome at machine learning
Making Developers Awesome at Machine Learning
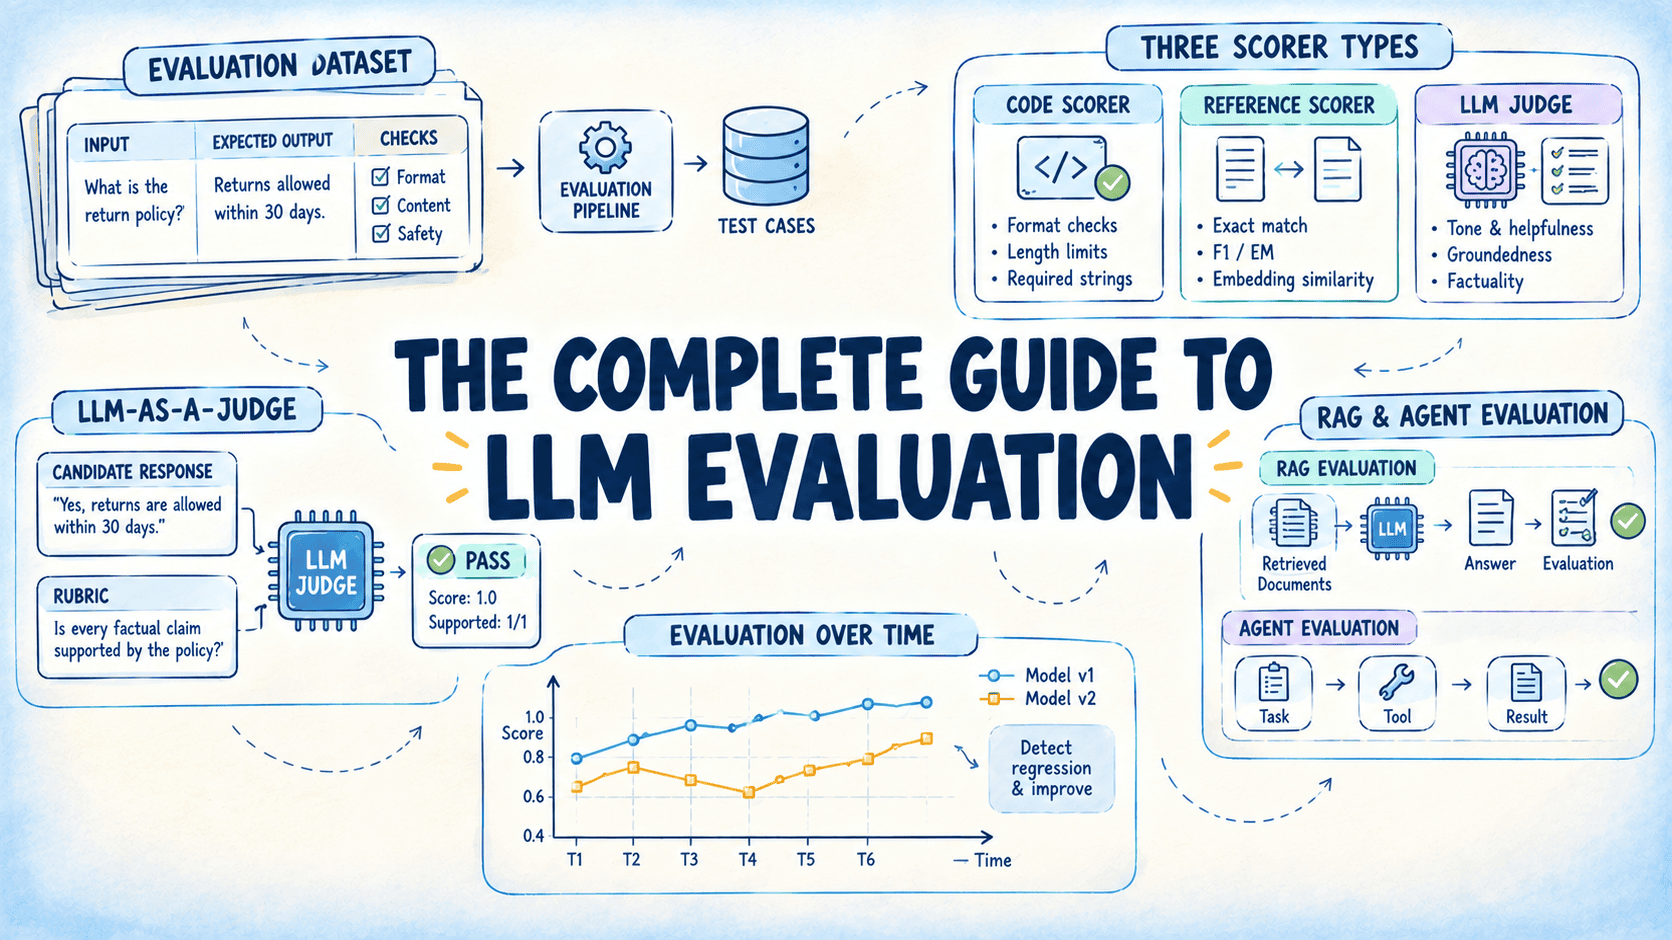
In this article, you will learn how to evaluate LLM applications systematically, from choosing scorers and designing reliable LLM judges to evaluating RAG systems and agents across the release cycle.
A transformer layer is built from familiar operations: linear projections, attention, normalization, activation functions, and residual additions. A direct implementation may launch a separate accelerator kernel for every operation and write every intermediate tensor to device memory. The mathematics is correct, but the execution can spend more time moving values and launching kernels than performing […]
In this article, you will learn how to get reliable structured outputs from large language models by validating them against a contract and the source text, retrying only when it helps, and constraining generation.
In this article, you will learn how to sandbox the code an AI agent writes by running it in a limited subprocess, a hardened Docker container, and a Firecracker microVM, and how to compare their safety and latency.
In this article, you will learn how diffusion language models generate text by iteratively refining a masked sequence, and how this differs from the token-by-token generation of GPT-style models.
Two transformer models with the same parameter count can have very different memory requirements during inference. A major reason is the structure of their attention layers. The number of key-value heads, the representation stored for each token, and the number of earlier tokens retained by each layer determine how much KV cache a request needs. […]
In this article, you will learn how to build a side-by-side benchmark of local and cloud LLM classifiers using Scikit-Ollama and a Groq-backed Scikit-LLM pipeline.
A model is a collection of numbers. The format used to store and compute with those numbers affects how much memory the model occupies, how quickly the hardware can move the numbers, and which arithmetic units can process them. Changing precision can therefore make inference faster without changing the model architecture. Lower precision is not […]
In this article, you will learn what DiffusionGemma is, how its diffusion-based text generation differs from standard autoregressive language models, and how to run it with Hugging Face Transformers and vLLM.
Sponsored Content From November 5 to November 20, 2026 (starting at 8:00 a.m. UTC), 365 Data Science will grant free access to its entire learning platform. This limited-time opportunity allows aspiring AI professionals and data enthusiasts to enhance their skills and gain practical, hands-on experience, completely free of charge. Tradition and […]
Welcome! I'm Jason Brownlee PhD and I help developers get results with machine learning. Read more
The EBook Catalog is where you'll find the Really Good stuff.
>> See What's Inside
Machine Learning Mastery is part of Guiding Tech Media, a leading digital media publisher focused on helping people figure out technology. Visit our corporate website to learn more about our mission and team.
© 2026 Guiding Tech Media All Rights Reserved
Making Developers Awesome at Machine Learning
Making developers awesome at machine learning
Making Developers Awesome at Machine Learning
In this article, you will learn how to evaluate LLM applications systematically, from choosing scorers and designing reliable LLM judges to evaluating RAG systems and agents across the release cycle.
A transformer layer is built from familiar operations: linear projections, attention, normalization, activation functions, and residual additions. A direct implementation may launch a separate accelerator kernel for every operation and write every intermediate tensor to device memory. The mathematics is correct, but the execution can spend more time moving values and launching kernels than performing […]
In this article, you will learn how to get reliable structured outputs from large language models by validating them against a contract and the source text, retrying only when it helps, and constraining generation.
In this article, you will learn how to sandbox the code an AI agent writes by running it in a limited subprocess, a hardened Docker container, and a Firecracker microVM, and how to compare their safety and latency.
In this article, you will learn how diffusion language models generate text by iteratively refining a masked sequence, and how this differs from the token-by-token generation of GPT-style models.
Two transformer models with the same parameter count can have very different memory requirements during inference. A major reason is the structure of their attention layers. The number of key-value heads, the representation stored for each token, and the number of earlier tokens retained by each layer determine how much KV cache a request needs. […]
In this article, you will learn how to build a side-by-side benchmark of local and cloud LLM classifiers using Scikit-Ollama and a Groq-backed Scikit-LLM pipeline.
A model is a collection of numbers. The format used to store and compute with those numbers affects how much memory the model occupies, how quickly the hardware can move the numbers, and which arithmetic units can process them. Changing precision can therefore make inference faster without changing the model architecture. Lower precision is not […]
In this article, you will learn what DiffusionGemma is, how its diffusion-based text generation differs from standard autoregressive language models, and how to run it with Hugging Face Transformers and vLLM.
Sponsored Content From November 5 to November 20, 2026 (starting at 8:00 a.m. UTC), 365 Data Science will grant free access to its entire learning platform. This limited-time opportunity allows aspiring AI professionals and data enthusiasts to enhance their skills and gain practical, hands-on experience, completely free of charge. Tradition and […]
Welcome! I'm Jason Brownlee PhD and I help developers get results with machine learning. Read more
The EBook Catalog is where you'll find the Really Good stuff.
>> See What's Inside
Machine Learning Mastery is part of Guiding Tech Media, a leading digital media publisher focused on helping people figure out technology. Visit our corporate website to learn more about our mission and team.
© 2026 Guiding Tech Media All Rights Reserved
本页为82搜索生成的网页快照,内容来自站内索引;演示数据的原文链接仅作示例。